Most arguments about whether coding agents should use test-driven development (TDD) assume a codebase that already has tests. Most of the systems we modernize don't.
Convective modernizes ColdFusion and Rails applications, and the usual starting point is little or no automated test coverage. On code like that, an agent should not start with TDD. It should start with characterization tests that pin down what the code does today, and use TDD for the change that comes after. The question that decides the outcome is not TDD or no TDD. It is whether anything in the repository defines correct behavior before the agent starts editing.
What Böckeler's TDD experiment found
Birgitta Böckeler's experiment found no clear quality gain when a coding agent followed TDD. On August 10, 2026, she published an evaluation of TDD inside the agent loop on martinfowler.com. Claude Sonnet 4.6 built solutions with and without TDD instructions, and Claude Opus 4.8 judged the results without knowing which workflow produced which. More than once the judge ranked the non-TDD solutions slightly higher on design and test quality, and mutation scores showed no sign that the TDD runs wrote stronger tests.
The explanation is the useful part. The non-TDD runs laid out the full design first: architecture, data types, edge cases, contracts. TDD instructions worked against that step. The agent made many small local decisions, one test at a time, and rarely went back to them.
Her setup matters too. Every task was greenfield, relatively small, and purely business logic. That is not the code we get handed.
Why TDD alone fails on legacy code
You cannot test-drive code that already exists. A 15-year-old ColdFusion application or an aging Rails monolith already does something, and real users depend on it, including the behavior nobody documented and the bug two customers now rely on. Tell an agent to TDD a change there and it writes tests against the implementation it just read. Those tests prove the code does what it does. They say nothing about what it should do.
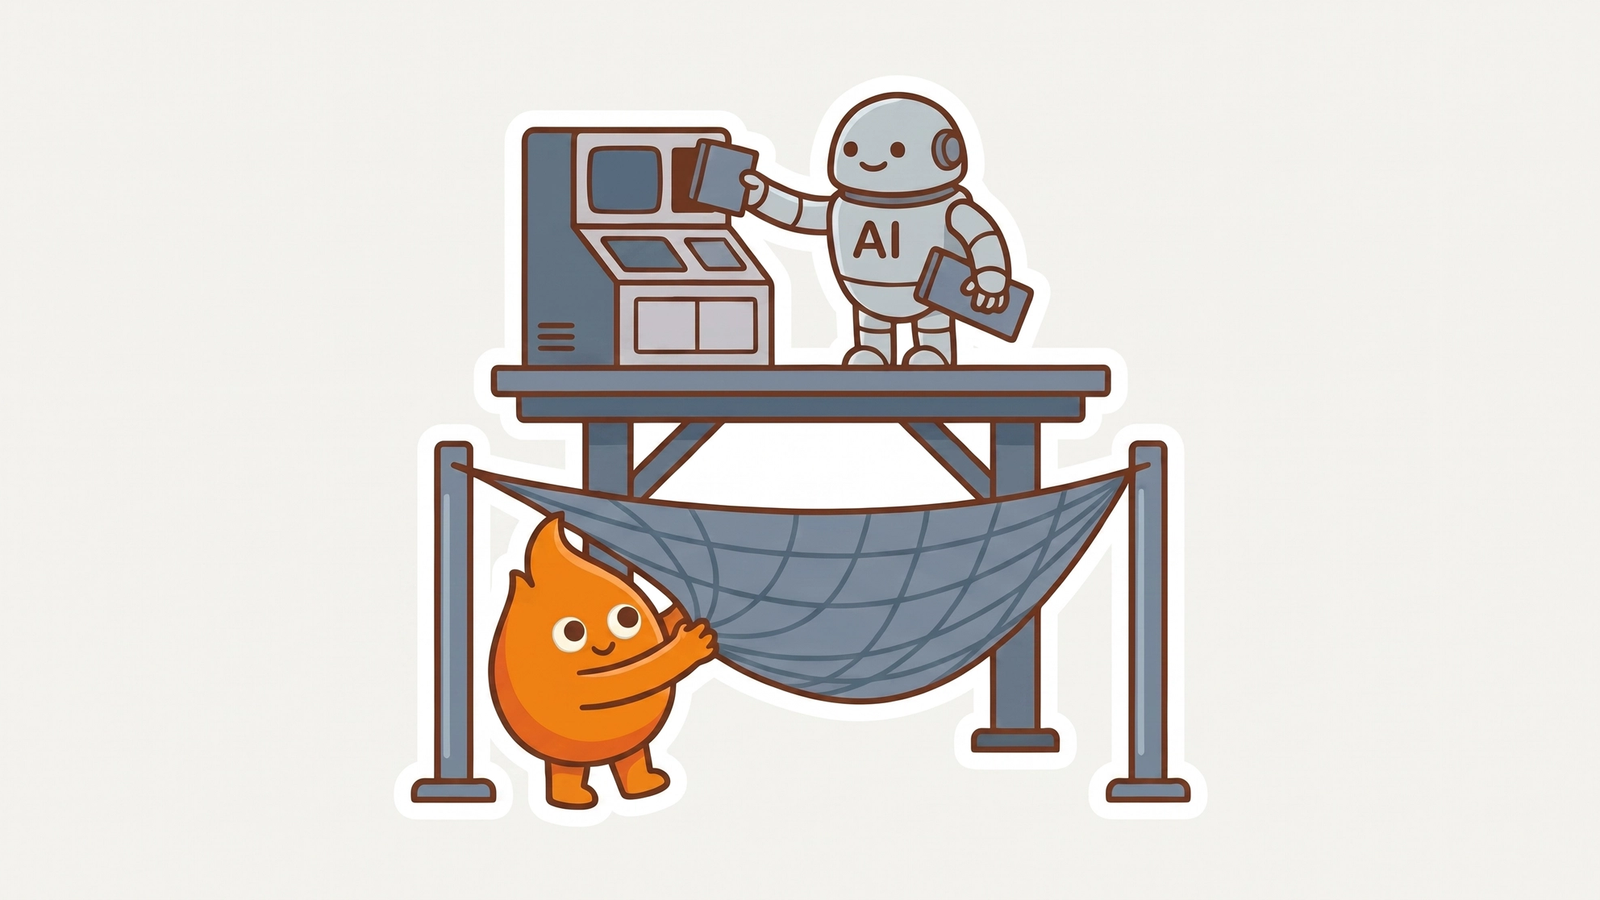
A characterization test is a test that records what existing code does right now, correct or not, so any later change to that behavior shows up as a failure. In Michael Feathers' words, its purpose "is to document your system's actual behavior, not check for the behavior you wish your system had." It is the net you put up before you change anything.
Should a coding agent use TDD on code with no tests?
Yes, but third. Characterization tests come first, a human review of them comes second, and TDD drives the change after that. This is the sequence we run when coverage is low.
Pin the current behavior. The agent writes characterization tests around the code it is about to change. These tests are not aspirational. They record present behavior, so a regression shows up the moment it happens.
Review what got pinned. A characterization test can lock in a bug. That is fine for a safety net and dangerous for a spec. A person confirms which pinned behaviors are intended before any of them becomes the definition of correct. This is the kind of review work that becomes the bottleneck once agents write the code, so staff for it.
Then test-drive the change. With the net in place, a failing test for the new behavior earns its keep. Its red step now fails against verified existing behavior, not against the agent's fresh guess.
What makes a failing test mean something
A failing test proves something only if someone checks why it failed. Böckeler says it directly: when the agent writes the test and also confirms the failure, "a red test tells you the agent ran it and saw failure, not that the failure was for the right reason." On legacy code, the reviewed characterization suite gives that red step a fixed reference to fail against.
The broader lesson: telling a model exactly how to work is usually a losing game. The durable investment is whatever lets you check the result. On a small greenfield problem, that can be a mutation score. On a system you inherited, it is a characterization suite, because without one neither the agent nor your team knows what the code did before the change.
The teams that get burned copy an agent's testing ritual and skip the part that doesn't fit their codebase. The same principle sits behind grounding AI modernization in evidence rather than plausibility. If you are about to point agents at an older ColdFusion or Rails codebase, defining correct behavior is the work we scope first.