The usual response to a rising AI bill is to treat it as a spending problem. Finance gets a dashboard, engineering gets a monthly cap, and the number keeps climbing. The tools are real. They do not touch what sets the number.
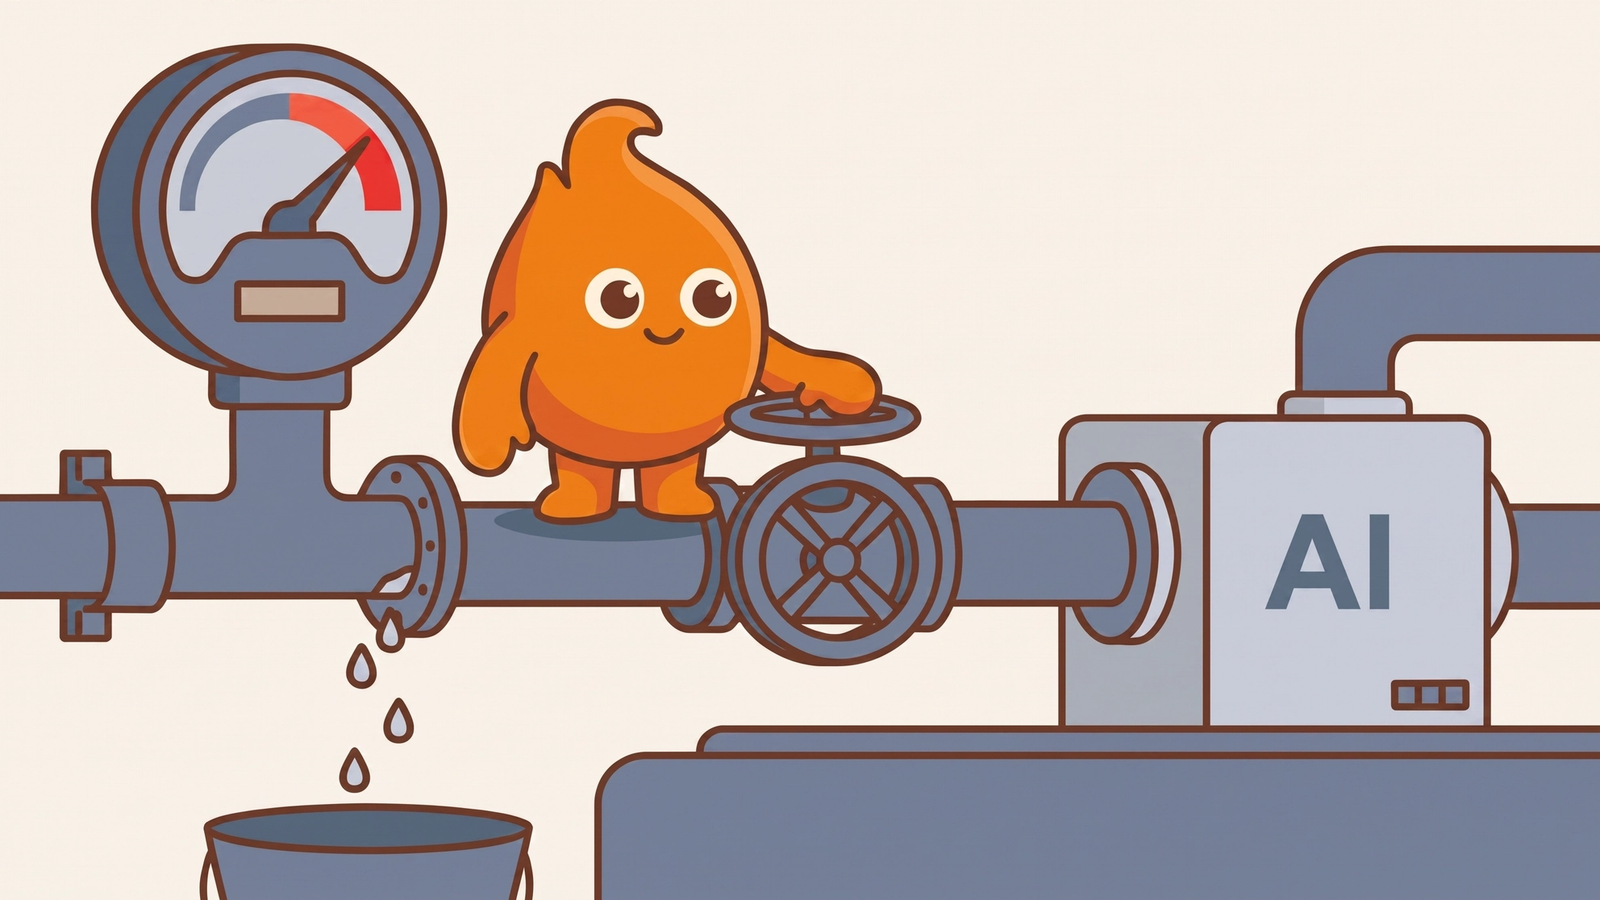
The way to reduce AI token costs is upstream, in how the pipeline is built: which model handles each task, what goes into the context window, what gets cached, and how much code the agent has to read. Spend controls tell you the bill is high. Architecture decides how high it is.
We run production agentic delivery pipelines and pay these bills ourselves. By the time a token cost reaches procurement, the pipeline design has already priced it.
What AI spend controls do, and what they cannot
Spend controls give you visibility and a ceiling; they do not change what a unit of work costs. On July 16, 2026, Ramp launched AI token spend controls that break spending down by provider, team, and API key, with limits and alerts on unusual spikes. On August 3, 2026, GitHub added a reasoning-level setting for Copilot cloud agent, so a team picks how much the model reasons, and how many tokens it spends, when it starts a task.
Both are useful. Neither changes how many tokens a given change consumes. A dashboard tells you the bill is high. It does not tell you the bill is high because the agent rereads a 17,000-line file on every change.
Where token cost is actually set
Token cost is set by four pipeline decisions, and each one moves the bill more than a cap does. The measure that matters is cost per unit of work: the tokens one task, such as one code change or one processed document, consumes from start to finish.
Model routing. Sending every task to the top model is the most common overspend we see. Anthropic's published price list puts the input rate of its largest model at ten times that of its smallest. Most tasks do not need the top tier. Route by task, not by default.
Context discipline. An agent pays to read its context on every turn. Loading the whole repository into the window feels thorough and bills like it. What you feed the agent, and what you keep out, is a cost decision.
Caching. On the same price list, a cache hit is billed at a fraction of the standard input price. Repeated work that hits the cache is cheap. Repeated work that misses it pays full price every time. Whether your pipeline caches is architecture, not procurement.
Code the agent has to read. This is the one nobody prices. In an experiment published July 30, 2026, Thoughtworks' Giles Edwards-Alexander refactored one oversized data access layer and cut the input tokens for the same change by 83 percent, because the agent could read fewer files. We cover how to run that measurement in refactoring ROI, measured in tokens, and the code patterns behind it in five ways sloppy code inflates your AI coding bill.
When we review a pipeline with a high bill, we start with routing and context. Those changes ship quickly and touch no application code. The code work comes next, and it pays back on every change after it.
Why is this the cloud-cost mistake again?
AI spend is repeating the early cloud pattern, where tools bought visibility and engineering bought the savings. Around 2015, companies moved to the cloud, watched the bill climb, and reached for cost dashboards and reserved-instance brokers. The dashboards helped at the margin. The real savings came from teams that learned the bill was an output of architecture: instance sizing, data transfer, and what got left running overnight.
Spend caps and credit markets are this cycle's reserved-instance brokers. They are worth having. They are not the lever. The lever is a pipeline that routes cheaply, feeds context sparingly, caches aggressively, and runs against code that is cheap for an agent to work in.
Who should own the AI bill
Engineering should own the fix, even when finance owns the budget. Finance can cap spend, but finance cannot refactor the data layer, tune the model router, or decide what goes into the context window. If the only response to a high bill is a tighter cap, the underlying cost never moves. It gets rationed.
The dashboard is a good place to notice the problem and a bad place to fix it. That work is upstream, and it is where our AI implementation framework starts when the bill is the symptom.