The kickoff goes well until the slide with the number. The sponsor has told the board that AI will make engineering ten times more productive. Sometimes the number is one hundred. Everyone in the room knows it came from nowhere in particular, and nobody in the room will say so. So the scope gets written to a number nobody believes, and the project is mispriced before any code is generated.
The way out is not courage in the kickoff meeting. It is metric selection: accept the ambition, then measure accepted work instead of generated work. Accepted work is a change that has been reviewed, merged, verified, and used. We scope AI acceleration engagements for mid-market executive sponsors, so we work inside this problem, not beside it.
How do you measure AI productivity without contradicting the sponsor?
You give the multiplier a denominator. Ten times more productive, measured how? Lines generated? Features shipped? Revenue per engineer? Without a denominator, nobody can be wrong, and the number stays alive and unmet two years later.
So you do not call the number impossible. You say: here is how we will know it is working, and you propose measures the sponsor cares about and engineering cannot game.
In a randomized controlled trial METR published on July 10, 2025, 16 experienced open-source developers took 19% longer to finish their issues when they could use AI tools. Afterward, they still believed AI had sped them up by 20%. METR calls it a snapshot of early-2025 tools. The perception gap is the lasting lesson. If the people doing the work can misjudge the effect in size and direction, a sponsor's multiplier is not evidence.
Measure accepted work, not generated work
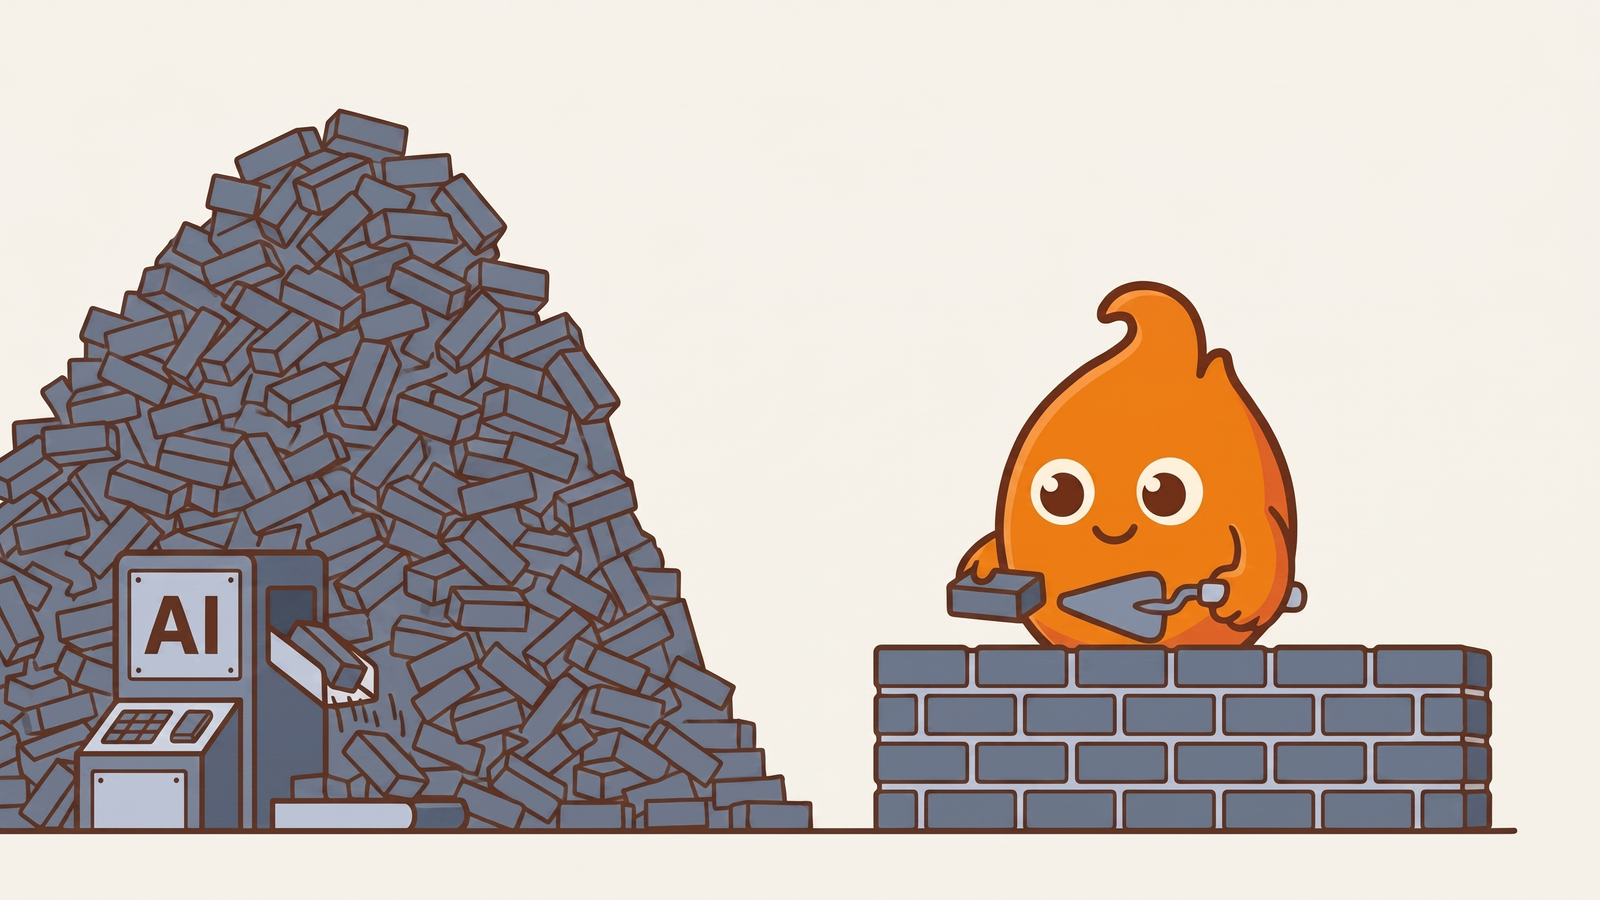
Generation metrics are the trap. Lines produced, pull requests opened, and tokens consumed all jump the day AI arrives, and none of them is delivery. Code that is generated but not reviewed, integrated, and shipped is inventory, and inventory with a defect rate.
The measures that hold up sit on the acceptance side of the pipeline:
Time from request to merged, verified change. Measure the full cycle, not the generation step. This is the number the business feels.
Review cycles per change. Count the round trips before a reviewer accepts the work. If AI-assisted changes need more cycles than before, the assistance is creating rework before the merge.
Adoption of what shipped. Check whether people use what you delivered. A growing pile of shipped, unused features is the multiplier failing quietly, and no velocity chart will show it.
Escaped defect trend. Track the defects found after release. Speed bought with quality debt comes due next quarter, when the program's credibility can least afford it.
None of these contradict anyone. Together they turn the slogan into a funnel you can improve and report quarter by quarter.
Capture a baseline before the tooling lands. Without one, any post-adoption number can be narrated as a win. One or two months of data on the same four measures turns the later conversation from persuasion into subtraction, and executives trust subtraction. If the tooling is already deployed, rebuild what you can from version control and ticket history.
Scope the engagement against the binding stage
The binding stage is the step in the delivery pipeline where work waits longest. Speeding up any other step does not speed up delivery, so you size the engagement against that stage.
On most teams that adopt AI heavily, the binding stage is no longer generation. The queue forms at review, integration, and verification, where senior attention is scarce and the new volume lands. The 2024 DORA report found the same tension at industry scale: AI adoption raised individual productivity, flow, and job satisfaction, but it hurt software delivery stability and throughput. Scoping "more generation capacity" for a team whose review queue is already full is how a 100x mandate produces a barely measurable result and a warehouse of stalled branches.
That is also the answer to "why not just buy more seats?" Seats speed up the stage that is rarely the constraint. The work that moves the funnel is verification design, integration discipline, and pipeline sequencing. It is the same reason most AI pilots waste the budget: they test the impressive constraint instead of the binding one. If review is your binding stage, read why the bottleneck moved to review and how to staff for it.
Keeping the sponsor whole
The sponsor who announced the number is the budget, and usually the person who most wants the initiative to succeed. Frame the metric conversation as protection for their announcement: a funnel that shows compounding acceleration each quarter survives a board meeting, and a stalled moonshot does not. You are not lowering their number. You are giving it a denominator it can survive.
What kills projects is the opposite move, and we have watched it happen. The team privately re-scopes to what it believes is possible while it publicly reports against the slogan. The gap widens for two quarters, then becomes a credibility event for everyone, sponsor included. The mispricing was never corrected. It was deferred, with interest.
Say yes to the ambition, propose the instrumentation, and report the funnel. If you are scoping AI work against an expectation that arrived pre-inflated, our AI implementation framework is how we run it. AI that ships, not AI that demos.